In September, a marketer testing several AI visibility tools posted in r/SEO_LLM that the numbers didn't line up at all. One tool made a brand look healthy while another made it look nearly invisible.
Does anyone trust AI visibility scores between different tools?
Testing a few AI visibility tools right now and the numbers don't line up at all. I'm not even talking about small differences. One can make a brand look pretty healthy while another makes it look nearly invisible. I assume a lot comes down...
Most replies pointed to the same cause. Different tools use different prompts and methods, so their raw scores can't be compared. One commenter suggested asking any tool how much its score moves when nothing has changed, before trusting what it says when something has.
We ran into the same problem from another angle. When we scored the same set of AI answers three different ways, the leading brand changed. This guide explains what goes into an AI visibility score and why the formula matters as much as the data. Then it shows how to build a score you can defend. Sources were checked on September 27, 2026.
What an AI visibility score measures
An AI visibility score is a summary. It compresses several measurements, taken across a set of questions and AI engines, into one number, usually on a scale from 0 to 100.
The measurements underneath are fairly standard. Mention rate is how often answers name your brand, and citation rate is how often they link to your site. Share of voice compares your mentions with those of named competitors. Some scores also weight position in the answer or sentiment.
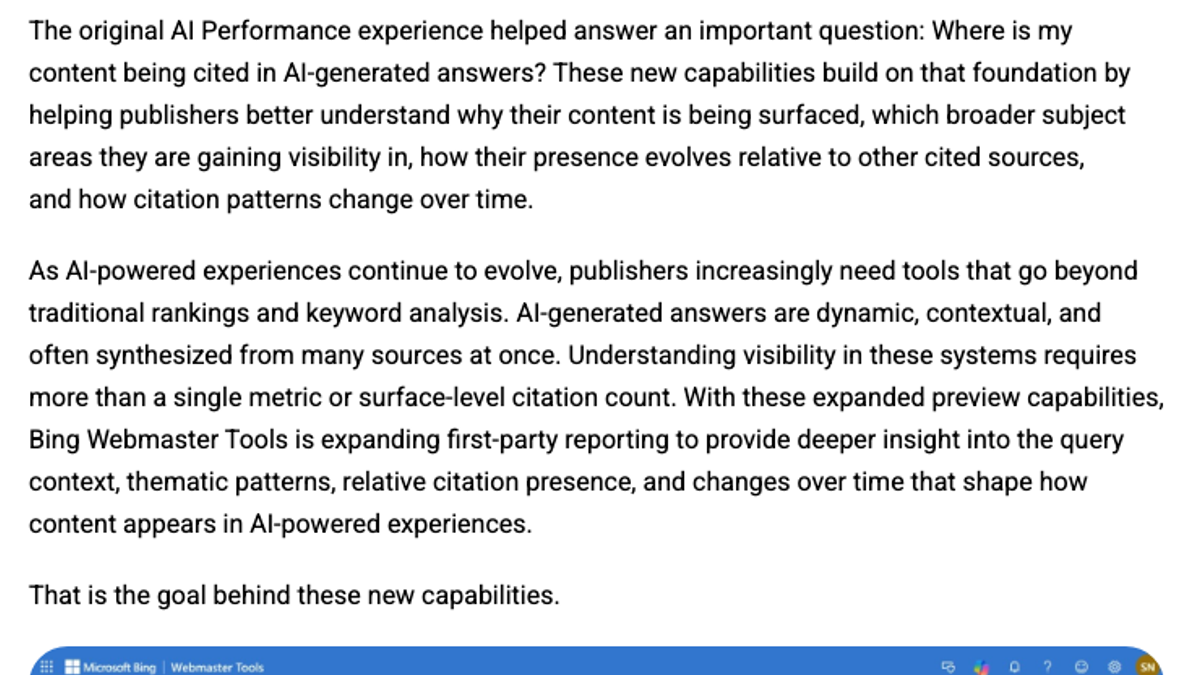
Semrush, for example, describes its AI Visibility Score as a 0 to 100 benchmark of a brand's share of presence in AI answers, measured against the median of its competitors. Bing Webmaster Tools reports a narrower metric, citation share, which is your site's percentage of all citations shown for a given query. When Bing added it in June, it also cautioned against leaning on one number:
Before relying on any score, find out which of these measurements it includes and how it weights them.
Built by the team that got cited in 48 hours.
Content generation, backlink building, AI visibility tracking, and Google rankings. One platform, zero guesswork.
Same answers, different leader
To see how much the formula matters, we took 25 AI answers we collected on September 26. They came from five help desk buying questions, asked three times on OpenAI's API and twice on Perplexity's, and we scored 13 help desk brands three ways:
| Brand | Score A: mentions only | Score B: half mentions, half citations | Score C: weighted by position |
|---|---|---|---|
| Freshdesk | 88 | 56 | 45 |
| Help Scout | 80 | 48 | 63 |
| Zendesk | 68 | 46 | 43 |
| Zoho Desk | 76 | 40 | 32 |
Score A is the share of answers that named the brand. Score B averages that with the share of answers that linked to the brand's own site. Score C gives more credit for being named first or second.
Freshdesk leads on mentions and on the blended score. Help Scout leads when position counts, because it was named first in 10 of the 25 answers, against 3 for Freshdesk. Zoho Desk drops behind Zendesk as soon as citations count, since its site was linked in only one answer.
We call this the formula gap: the change in a brand's standing caused only by how a score is weighted, with the underlying answers held constant. Every tool makes weighting choices. Two tools can measure the same answers accurately and still disagree, because they value different things.
None of the three formulas is wrong. Each answers a different question, from how often you're named to how prominently you appear, so pick the one that matches the decision you need to make and keep it fixed.
Position deserves particular caution. SparkToro's January research found that AI tools almost never list the same brands in the same order twice. A score that rewards being named first moves with that noise. It's also easily skewed by the question set. Zendesk's position score in our data is lifted by a question that asks for Zendesk alternatives, where answers mention Zendesk first by default.
What to put in a score you can defend
A defensible score has two properties. You can see its parts, and it only moves when the answers themselves change.
These components meet that bar:
| Component | How to calculate it | Why it belongs |
|---|---|---|
| Mention rate | Answers naming you divided by all answers | Presence is the most stable signal across runs |
| Citation rate | Answers linking to your site divided by all answers | Shows whether engines use your pages as sources |
| Share of voice | Your mentions divided by mentions of all tracked brands | Shows your position against a fixed set of competitors |
| Accuracy | Pass or fail on a brand question about price and fit | A score means little if the answers describe you wrongly |
Leave position out of the headline number, or report it separately with a warning that it's noisy. Keep the weights simple and fixed, so a change in the score always means a change in the answers. An equal average of mention rate and citation rate is easy to explain in a meeting.
Report the parts next to the score, every time. A blended number can hide a rising mention rate and a falling citation rate, which call for different fixes. Our guide to an AI visibility dashboard shows how to lay those parts out. Our note on why we track seven engines instead of one score covers splitting results by engine.
See your first AI citation report in under 5 minutes.
No setup calls. No onboarding meetings. Connect your domain and see where AI mentions your brand right now.
Why scores from different tools don't match
Before comparing any two scores, check what each one measured. These are the usual differences:
| Difference | Why it changes the score |
|---|---|
| The question set | Branded or narrow questions inflate scores; broad category questions lower them |
| Engines covered | Brands can be strong on one engine and weak on another |
| Runs per question | A single run carries more noise than an average of several |
| Location and account state | Answers vary by country, and logged-in memory can personalize them |
| What counts as a mention | Exact name matching and entity matching give different counts |
| The formula | Weighting mentions, citations and position differently changes the ranking |
Another thread in r/SEO_LLM, about finding the noise floor before trusting a score, added one more safeguard. Keep a control set of questions and competitors you never optimize for, and count a gain only if it beats whatever the control set did in the same period. Answers can shift across the board for reasons unrelated to your work.
How to calculate your own score
You don't need a tool to produce a score you can defend. You need a fixed method.
Start with 25 to 50 questions buyers ask before they know your name, and keep the list fixed. Run each one at least twice on at least two engines. For each answer, record whether your brand is named and whether your site is linked, along with the competitors that appear.
Then calculate your mention rate and citation rate, and average them. Using the numbers above, Help Scout was named in 80% of answers and linked in 16%, for a score of 48. Recalculate monthly with the same questions, engines and formula.
Mind the sample size. Even with 100 answers per check, a month-to-month change of up to about 14 points can be chance. Our guide to tracking AI citations for free covers how many answers you need before a change means something.
What a score can't tell you
A visibility score measures presence in answers. It doesn't measure what that presence is worth, since most AI mentions never produce a click. Pair the score with branded search impressions and AI referral visits. A "How did you hear about us?" field on demo forms helps too. Our comparison of ChatGPT citations and AI referral traffic covers how to report the two together.
It also can't tell you what to fix. For that, look at the questions where you're missing and the sources the engines cite instead.
Done by hand, checking 50 questions on seven engines takes about six hours a week, and publishing eight solid articles a month to close the gaps takes 16 to 24 hours more. Those are rough estimates.
RankControl's AI visibility tracking runs your 50 questions every week on seven engines, marks each one as mentioned, cited or both, and records which competitors and sources each engine used. The content engine writes each article against the pages already ranking for its keyword and publishes it on your own domain.
You can build this score with a spreadsheet and a fixed question list. Or RankControl's agents can run the checks every week while your team works on the questions where you're missing.
Your competitors are building backlinks while you read this.
Organic outreach, social mentions, and citations from Editorial Circle member sites, with managed backlinks available as an add-on. Grow your domain authority without running the campaign yourself.