When we requested Forbes' homepage on October 19, 2026, as a normal browser, we got the page. When we sent the same request claiming to be GPTBot, OpenAI's training crawler, Forbes answered with HTTP status 402, "Payment Required." X did the same to GPTBot and to ChatGPT-User.
That's where bot traffic stands in 2026. Bots now make up more than half of web traffic, AI bots are the fastest-growing slice, and big sites have started to charge them, block them or wave some through.
This roundup collects the newest numbers from Thales, Cloudflare and HUMAN Security, and adds our own test of how 244 of the web's top sites answer when a request says it's an AI bot. Our AI crawler access statistics cover what sites say in robots.txt, and this post covers the traffic itself.
Bot traffic statistics at a glance
| Measure | Figure | Source |
|---|---|---|
| Share of all web traffic from bots, 2025 | More than 53% | Thales 2026 Bad Bot Report |
| Same measure, 2024 | 51% | Thales |
| AI bots' share of HTML page requests, 2025 average | 4.2% | Cloudflare Radar Year in Review |
| Googlebot's share of HTML page requests, 2025 | 4.5% | Cloudflare |
| Growth in AI-driven traffic, January to December 2025 | 187% | HUMAN Security |
| Growth in AI agent traffic, 2025 | 7,851% | HUMAN Security |
| Growth in user-triggered AI crawling, 2025 | More than 15x | Cloudflare |
| Top 244 sites refusing a request claiming to be GPTBot, Oct 2026 | 31 (12.7%) | Our test |
The headline figures vary because each source measures something different. Thales counts all traffic it protects, Cloudflare often counts only requests for web pages, and HUMAN measures growth rather than share. Each section says which one it is.
How much of the web is bots
The longest-running measure is Thales' Bad Bot Report, formerly Imperva's. Its 2026 edition, published in April, found bots made up more than 53% of all web traffic in 2025, up from 51% in 2024. Human activity fell to 47%.
Thales calls that a structural shift rather than a spike. Its 2025 edition, covering 2024, was the first in a decade where automated traffic passed human traffic, and the gap widened in 2025.
Cloudflare's view is narrower and more useful for a website owner. In its 2025 Year in Review, it classified requests for HTML pages, the pages people actually read, as coming from humans, AI bots or other bots. Non-AI bots started 2025 making half of those requests, seven points more than humans. By December 2, humans made 47% and non-AI bots 44%.
So on the pages that matter for SEO, humans and bots are roughly even, and AI bots are a small but rising third group.
How much of it is AI
AI bots averaged 4.2% of HTML requests across Cloudflare's network in 2025. The share swung from 2.4% in early April to 6.4% in late June.
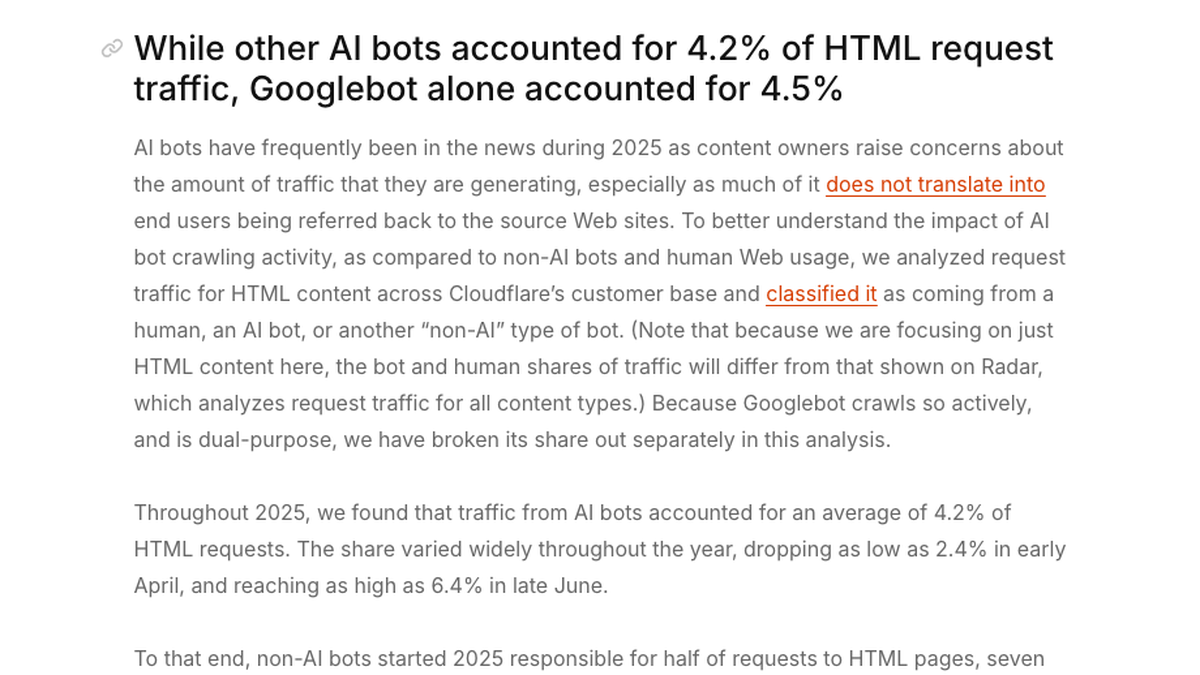
Googlebot sits apart, because it crawls for both Google Search and Google's AI. It alone made 4.5% of HTML requests, slightly more than all other AI bots combined, and peaked at 11% in late April.
Cloudflare's verified bot data shows who the big crawlers are. Googlebot made over 28% of verified bot traffic, GPTBot about 7.5% and Bingbot 6%. By category, search engine crawlers made 40%, AI crawlers 20% and SEO tools over 13%.
| Bot or category | Share of Cloudflare verified bot traffic, 2025 |
|---|---|
| Googlebot | Over 28% |
| GPTBot (OpenAI) | About 7.5% |
| Bingbot | 6% |
| All search engine crawlers | 40% |
| All AI crawlers | 20% |
| SEO tools | Over 13% |
See your first AI citation report in under 5 minutes.
No setup calls. No onboarding meetings. Connect your domain and see where AI mentions your brand right now.
Why AI crawlers crawl
Not every AI bot is after the same thing. Cloudflare sorts them by purpose into training, which feeds model building, search, which indexes pages for AI answers, and user action, which fetches a page when someone asks a chatbot a question.
Training dominates. At its peak, training crawling was 7 to 8 times search crawling and 32 times user-action crawling. But user-action crawling grew fastest, up more than 21 times from January to early December 2025.
That growth mostly tracked OpenAI's ChatGPT-User bot. Cloudflare noticed it developed a weekly rhythm from mid-February, with dips over the June to August school holidays, which it read as rising use at schools and workplaces. Our generative AI statistics show the same weekday pattern in Google searches for AI tools.
For site owners, this split matters more than the totals. A training crawler takes content and sends nobody back. A user-action fetch happens because a real person asked about something, and it's the kind most likely to end in a citation or a click.
AI agents are the new category
HUMAN Security's 2026 State of AI Traffic report, based on more than a quadrillion interactions, found automated traffic grew 23.51% in 2025, while human traffic grew 3.10%. That's about eight times faster.
Within that, AI-driven traffic grew 187% across the calendar year. Traffic from AI agents and agentic browsers, tools that browse and act on a person's behalf, grew 7,851% year over year. Most agents were exploring product listings, but a growing number reached user accounts and checkout pages.
| HUMAN Security finding, 2025 | Figure |
|---|---|
| Growth in automated traffic | 23.51% |
| Growth in human traffic | 3.10% |
| Growth in AI-driven traffic, January to December | 187% |
| Growth in AI agent traffic | 7,851% |
| Training crawlers' share of AI-driven traffic | 67.5% |
| Growth in AI scraper traffic | 597% |
| Share of AI scraper traffic aimed at media and streaming | 41% |
Training crawlers still made up 67.5% of AI-driven traffic, but their share fell through the year as AI scrapers grew 597%. HUMAN said 41% of AI scraper traffic targeted media and streaming, since AI search and news summaries need fresh content.
Which agents, and which industries
HUMAN's monthly tracking gives a closer look at the agents themselves. In April 2026, browser-based agents made up roughly 71% of the activity it observed from the top ten agents. Perplexity's Comet browser led with 48.12%, followed by OpenAI's Atlas at 21.33%, Anthropic's Claude Chrome extension at 17.33% and ChatGPT Agent at 8.55%.
| Industry | Share of AI agent traffic, April 2026 (HUMAN) |
|---|---|
| Media | 45.62% |
| Ecommerce | 38.20% |
| Travel | 14.12% |
Those three industries took 98% of agent traffic that month. About 70% of agent activity touched product and search pages, while 3.16% reached checkout and payment. So agents mostly read and compare today, and only a few buy.
If you sell online or publish news, these are the bots coming for you first. For a SaaS company, agent traffic is still small, though HUMAN saw it grow 41.5% in a month.
What AI crawlers send back
The complaint behind most of this is the exchange rate. Crawlers take a lot and send few people back. Cloudflare measures it with a crawl-to-referral ratio, the number of crawl requests for every visit referred to the site.
| Platform | Crawl-to-referral ratio, 2025 (Cloudflare) |
|---|---|
| Anthropic | About 25,000:1 to 100,000:1 after May, peaks to 500,000:1 |
| OpenAI | Spiky, up to 3,700:1 in March |
| Perplexity | Under 400:1 at peaks, under 200:1 from September |
| Microsoft | Peaks of about 50:1 to 70:1 |
| 3:1 to 30:1 | |
| DuckDuckGo | Under 1:1 for most of the year |
Perplexity sends the most back of the AI platforms, which matches its design of showing sources on every answer. Our search engine market share analysis has more on how these engines compare as traffic sources.
A small startup put numbers on this in an r/OpenAI thread in July. Its founder said 80% of their traffic was AI crawlers, with Meta's the biggest, and two referrals to show for it. A reply pointed out that a training crawler can't produce a referral by design, so the fair comparison is against the search and user-triggered bots.
In April, a developer's post in r/webdev drew more than 1,500 upvotes. Meta's AI crawler had requested their site 7.9 million times in 30 days, using over 900 GB of bandwidth before they noticed. In the replies, the poster said their robots.txt was set correctly and the crawler hammered parameter combinations anyway.
Meta's AI crawler scraped my site 7.9 million times in 30 days. 900+ GB of bandwidth and massive server logs before I noticed, cool cool cool.
Bad bots and where they come from
Not all of this is crawling. Thales found AI-driven bot attacks grew 12.5 times in 2025, and 27% of bot attacks now target APIs, where bots skip the website and talk to the backend directly. Financial services drew 24% of all bot attacks and 46% of account takeover attempts.
HUMAN found the same pressure on retail. 70% of the scraping attacks it observed targeted retail and ecommerce businesses.
Most bot traffic comes from cloud servers. Cloudflare found 40% of global bot traffic came from the United States, far ahead of Germany at 6.5%. Two Amazon Web Services networks produced 14.4% of bot traffic and two Google Cloud networks 9.7%.
Your competitors are building backlinks while you read this.
Organic outreach, social mentions, and citations from Editorial Circle member sites, with managed backlinks available as an add-on. Grow your domain authority without running the campaign yourself.
Our test: what top sites send to a request claiming to be an AI bot
Robots.txt says what a site wants. It doesn't say what a site does. So on October 19, 2026, we requested the homepage of each of the top 600 domains on the Tranco list, once with each of five user agents, a normal browser plus the four below.
| User agent we sent | Refused or blocked, both passes | Share of the 244 sites |
|---|---|---|
| GPTBot (OpenAI training) | 31 | 12.7% |
| ClaudeBot (Anthropic training) | 31 | 12.7% |
| Generic script ("python-requests") | 29 | 11.9% |
| ChatGPT-User (OpenAI, user-triggered) | 26 | 10.7% |
We counted only the 244 domains that returned a real page to a normal browser request, since many top domains are infrastructure with no homepage. We also re-ran every mismatch a second time and kept only sites that refused in both passes. Most refusals were 403 Forbidden, with a few 429 rate-limit and 451 codes.
Three findings stood out.
First, 19 sites refused at least one AI bot by name while serving our generic script normally. That's a deliberate rule about AI, not general bot protection. The list included CNN, Reddit, Forbes, IBM, Salesforce, Shein and X.
Second, six sites refused GPTBot but served ChatGPT-User, including Forbes, Nature, Springer and the IETF. They said no to training and yes to the bot that fetches pages for live answers. Only one site, Eventbrite, did the reverse.
Third, there's the 402 code. Forbes returned "Payment Required" to GPTBot and ClaudeBot, and X returned it to GPTBot and ChatGPT-User. Cloudflare launched a pay-per-crawl option in 2025, and a 402 is how a site tells a crawler there's a price.
There's an important caveat. Our requests came from one server and only claimed to be AI bots. Sites that verify bots by their IP addresses would treat us as an impostor, and real crawlers coming from OpenAI's or Anthropic's networks could get a different answer. So this measures rules keyed to a bot's name, the kind most sites use, not every block in place.
What robots.txt files say about AI bots
Cloudflare also checked robots.txt files across its top 10,000 domains through 2025. AI crawlers, led by GPTBot, ClaudeBot and Common Crawl's CCBot, were the user agents most often blocked from a whole site. Googlebot and Bingbot rules leaned toward partial blocks, usually closing off login pages and other areas that aren't content.
Allow rules were rarer, since allowing is the default. One exception grew fast. Allow rules for Google-Extended, the token that controls whether Google can use a site's content for Gemini, tripled during the year. More sites ended 2025 explicitly letting Gemini use their whole site.
That matches the split in our own test. Sites are drawing a line between training, which they increasingly refuse, and the bots that power answers, which many still want reading their pages.
What this means for your own traffic numbers
Most of this traffic never shows up in Google Analytics, which only counts visitors who run its JavaScript. Crawlers mostly don't, so GA4 undercounts them by design. Your server logs and CDN dashboard show them.
That cuts both ways. Your GA4 numbers aren't inflated by AI crawlers. But you also can't see from GA4 which AI bots read your pages, or whether they came back after you published something new. Our guide to auditing AI crawlers in your server logs shows how to find them.
The other risk is cost. If you pay for bandwidth by the gigabyte, a crawler like the one in the r/webdev post can add a real bill. Rate limits and parameter rules usually fix it without blocking search.
Should you block them?
There's no single answer, and the numbers above explain why. Training crawlers take a lot and send nothing back by design. Search and user-triggered bots take less and are how AI answers find and cite you.
The sites in our test that blocked GPTBot but let ChatGPT-User through made the split that fits most businesses. Blocking every AI bot also blocks the ones that bring people. Our guide on whether to block AI crawlers walks through the choice by site type.
Whatever you choose, check what your site actually does, as well as what robots.txt says. A CDN rule or firewall setting can block a bot your robots.txt invites, and several sites in our test did exactly that.
How we gathered these numbers
The Thales, HUMAN and Cloudflare figures come from their 2025 and 2026 reports and press releases, checked on October 19, 2026. Cloudflare's figures are from its 2025 Year in Review, published in December 2025, which covers its own network.
Our test used the Tranco top 1 million list, downloaded October 19, and requested each of the top 600 homepages once per user agent, then rechecked every mismatch. We only requested homepages and kept the load to a handful of requests per site.
Tracking the AI visits that matter
Bot statistics tell you about the web. Your own logs tell you about your site, and the useful question is narrower. Are the AI bots that cite pages reading yours, and are people arriving from AI answers?
You can piece that together from server logs and GA4 by hand each month. Or RankControl can do it for you. Its analytics count AI crawler visits and visits from AI answers separately, and its AI visibility tracking checks every week whether ChatGPT, Perplexity, Claude, Gemini, Grok and Google AI Mode cite you, while you focus on your product.
You're getting AI traffic. But do you know where it comes from?
RankControl credits every visit to the assistant that sent it: ChatGPT, Perplexity, Claude, Gemini, Copilot, or Grok. Full source attribution, next to your Google traffic.