A commenter in r/DigitalMarketing found out the hard way that OpenAI's AI crawlers come in more than one flavor. They'd deliberately blocked GPTBot. Checking their robots.txt afterward, they found OAI-SearchBot blocked too, a leftover from a template copied two years earlier. ChatGPT's search had been told to stay away the whole time.
That's what goes wrong when someone asks what AI crawlers are and expects one answer. The phrase covers several bots doing different jobs, and robots.txt rules apply to each by name. This guide sorts them by job and shows what they do on a site. Every vendor page here was read on October 19, 2026.
What are AI crawlers?
AI crawlers are bots run by AI companies that request pages from your website. Each one handles one of three jobs. It collects pages that may train a future model, builds the search index that AI answers draw from, or opens a page because a person just asked a question. Most big vendors now run a separate bot for each job.
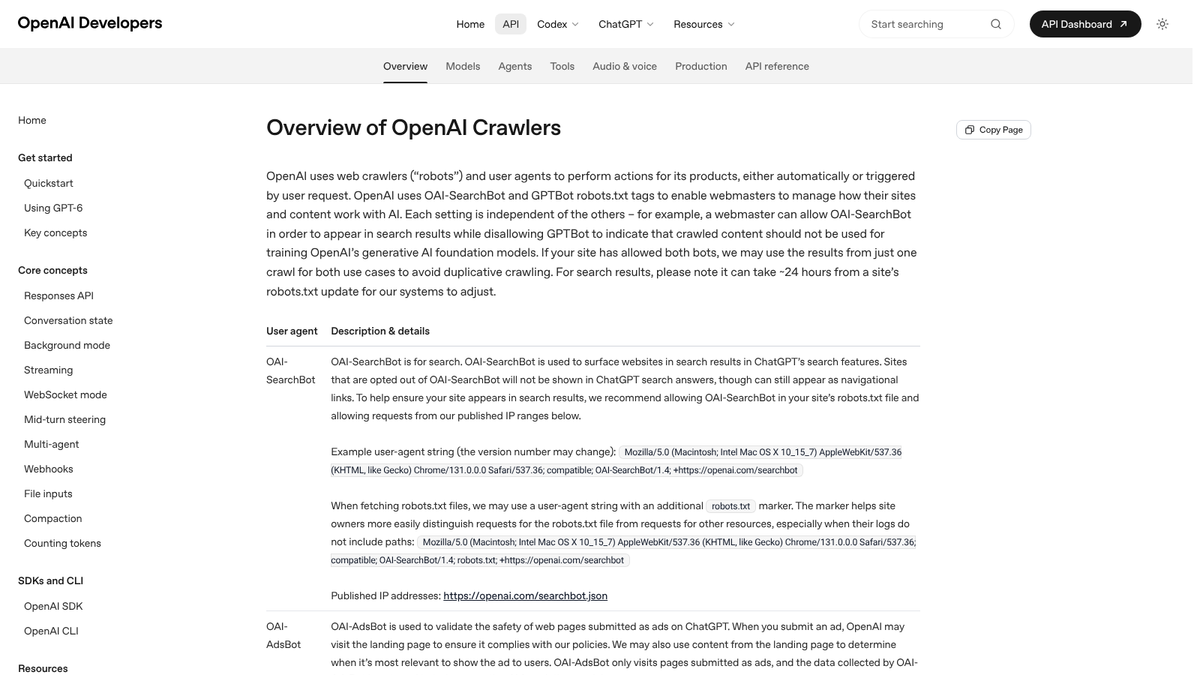
That last point matters most. GPTBot, OAI-SearchBot and ChatGPT-User are three different bots with three different names, so "block AI crawlers" is never a single switch. Call it the job test: before writing any rule about a bot, figure out which of the three jobs it actually does, then decide.
The three jobs, one bot each
Training crawlers gather pages in bulk. Whatever they collect may shape a future model, and nothing about that crawl sends a visitor back to your site. GPTBot, ClaudeBot and Meta's main crawler all work this way.
Search crawlers build an index, much the way Googlebot does for Google. ChatGPT, Claude and Perplexity look inside that index when searching for an answer, so blocking one makes your pages harder for that engine to find.
User-triggered fetchers only show up when someone asks a question and the engine decides your page might answer it. A visit from ChatGPT-User or Perplexity-User usually means a real person asked something seconds earlier.
OpenAI's crawler overview spells this independence out. You can allow OAI-SearchBot for search results while leaving GPTBot disallowed, and a robots.txt change takes about 24 hours to reach OpenAI's systems.
The main AI crawlers by vendor
Here's every major bot, its job, and what the vendor's page says about robots.txt. The last column is whatever date is printed there. Only three of the eight vendors print one, so for the rest there's no telling when the policy last changed.
| Bot | Vendor | Job | Follows robots.txt, per the vendor's doc | Doc date |
|---|---|---|---|---|
| GPTBot | OpenAI | Training | Yes | None shown |
| OAI-SearchBot | OpenAI | Search index | Yes | None shown |
| ChatGPT-User | OpenAI | User fetch | Rules "may not apply" | None shown |
| ClaudeBot | Anthropic | Training | Yes | April 7, 2026 |
| Claude-SearchBot | Anthropic | Search index | Yes | April 7, 2026 |
| Claude-User | Anthropic | User fetch | Yes | April 7, 2026 |
| PerplexityBot | Perplexity | Search index | Yes | None shown |
| Perplexity-User | Perplexity | User fetch | "Generally ignores" it | None shown |
| Meta-ExternalAgent | Meta | Training and indexing | Not stated | None shown |
| Meta-ExternalFetcher | Meta | User fetch | "May bypass" it | None shown |
| Applebot | Apple | Search index, may train | Yes | September 4, 2026 |
| Applebot-Extended | Apple | Training opt-out token | Read by Applebot | September 4, 2026 |
| Google-Extended | Training opt-out token | Read via Googlebot | October 15, 2026 | |
| CCBot | Common Crawl | Public web archive | Yes | None shown |
| Bytespider | ByteDance | Training, per outside reports | No vendor doc found | None |
Know exactly what AI says about your competitors.
RankControl's Recon Agent monitors competitor citations across ChatGPT, Perplexity, Claude, Gemini, Grok, Google AI Mode, and Google AI Overviews. See where they show up and you don't.
Two of those rows aren't actually crawlers. Google's page on its common crawlers says Google-Extended has no user agent of its own; crawling still happens through Googlebot, and the token only decides whether those pages may train Gemini or ground its answers. Google adds that it "does not impact a site's inclusion in Google Search nor is it used as a ranking signal."
Apple built the same kind of thing. Its Applebot page states plainly that "Applebot-Extended does not crawl webpages." It only tells Apple whether pages Applebot already fetched may train its models, and blocked pages can still turn up in Apple's search results.
Per Perplexity's bot docs, neither of its bots trains models, so blocking PerplexityBot only costs you search visibility there. For every user agent string and IP list, our complete AI crawler list has the full rundown.
Where the vendors disagree
Training and search bots from every big vendor claim to follow robots.txt. The real split shows up with user fetches. OpenAI says rules may not apply to ChatGPT-User "because these actions are initiated by a user." Perplexity says much the same about Perplexity-User, and Meta flags its own fetcher as one that may bypass the rules.
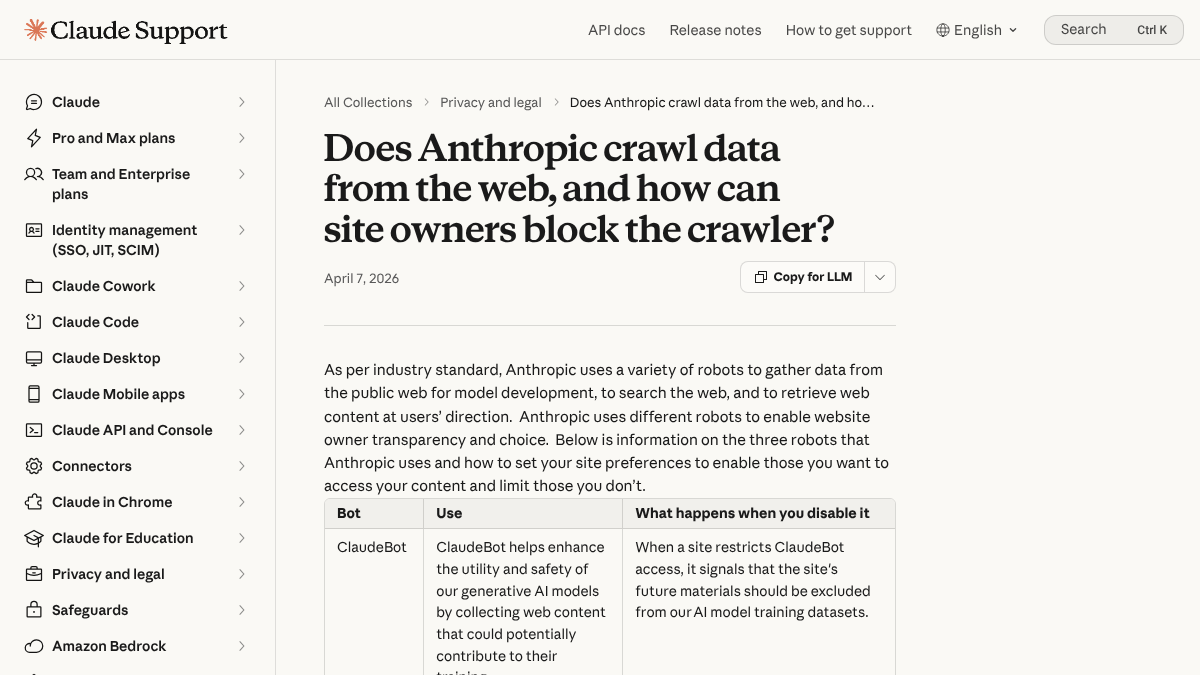
Anthropic took the opposite side. Its support article, last updated April 7, 2026, says its bots "respect 'do not crawl' signals" in robots.txt, covering all three, Claude-User included. It's the one genuine split between the big vendors here.
A written policy and an actual visit can still part ways, though. On r/neocities, a site owner asked Claude Code to read pages their robots.txt blocked, and it fetched them anyway, then apologized. One reply asked whether the file even named Claude-User, since a rule only covers whichever bots it names.
so AI crawlers just ignore your robots.txt and apologize when confronted lol
my company gives me access to claude code for work and I tried to see if it will respect my robots.txt that explicitly blocks ai crawlers and what not and surprise surprise, they really don't care lol I'm thinking of starting to poison all...
So treat robots.txt as a request that well-run bots choose to honor, nothing more. A hard stop has to happen at your firewall or CDN instead.
What AI crawlers do on your site
The best public data on crawler behavior is already getting old. Vercel and MERJ published their study of traffic across Vercel's network on December 17, 2024, so treat it as a snapshot from nearly two years back.
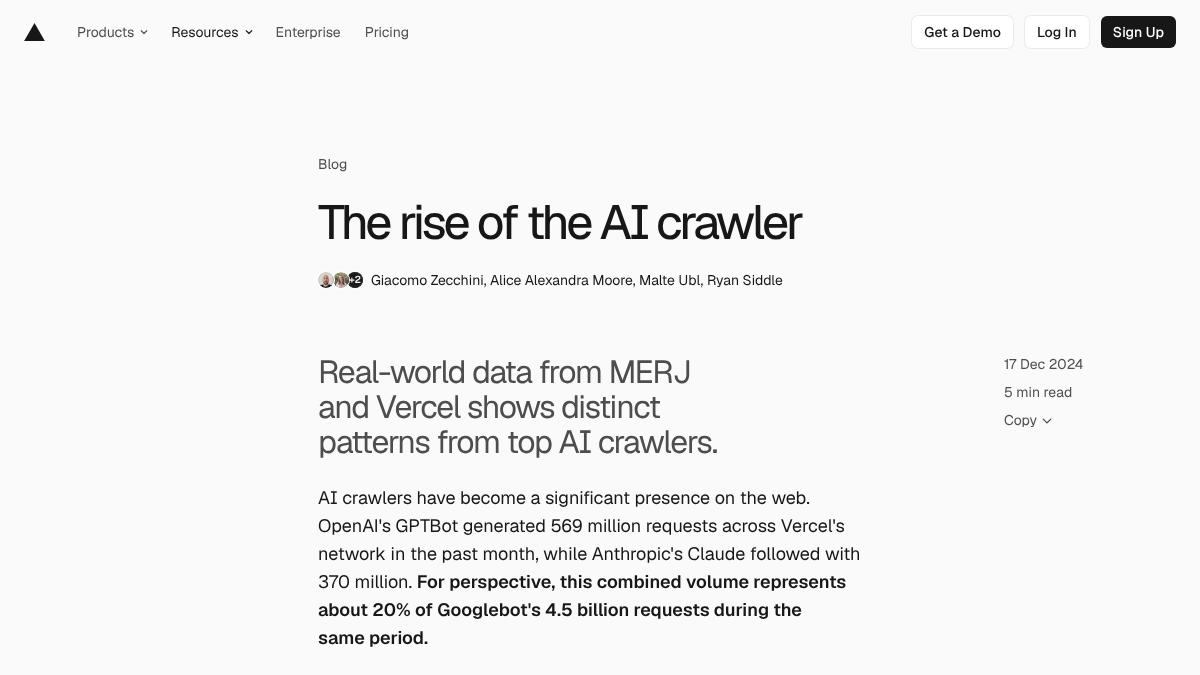
Vercel counted 569 million requests from GPTBot and 370 million from Claude's crawler in a single month, together about a fifth of Googlebot's volume on that network.
JavaScript was the bigger finding. ChatGPT's crawler fetched script files in about 12% of its requests and Claude's in nearly 24%, but neither ran them. A page that only shows real text after scripts execute shows those bots an empty shell. Gemini and Applebot were the exceptions, since both run on Google's and Apple's own rendering systems.
They were sloppy too. About a third of requests from both ChatGPT's and Claude's crawlers hit 404 pages, against roughly 8% for Googlebot. The lesson is to serve key content as HTML from the server and keep old URLs redirecting.
Volume alone can become its own problem. A developer on r/webdev posted that Meta's crawler hit their site 7.9 million times in 30 days and burned through more than 900 GB of bandwidth. Their robots.txt rules were ignored, and they confirmed the requests came from Meta's own IP range. Meta's docs only flag its fetcher as one that may skip robots.txt.
Meta's AI crawler scraped my site 7.9 million times in 30 days. 900+ GB of bandwidth and massive server logs before I noticed, cool cool cool.
26 content formats. Published on your domain. Matched to your brand.
Guides, comparisons, listicles, case studies, and more. RankControl generates content that gets cited by ChatGPT, Perplexity, Claude, Gemini, Grok, Google AI Mode, and Google AI Overviews.
The mix is shifting toward answers
Training made up nearly 80% of all AI crawling on Cloudflare's network in its August 2025 analysis. That balance is starting to tilt. TollBit's State of the Bots data, reported by The Register in February, found roughly one AI bot visit for every 31 human visits by late 2025, against one in 200 early that same year.
The jobs moved at different speeds. Between the second and fourth quarters of 2025, TollBit saw search indexer traffic climb 59% and retrieval bot traffic rise by about a third, while training scrapers fell 15% over that stretch. TollBit only counts sites using its own service, not the whole web, but the pattern holds: bots tied to live answers are the ones still growing. Our guide to auditing AI crawlers in server logs has the commands for checking your own numbers.
Cloudflare's rules, in order
On sites behind Cloudflare, its defaults often decide things before anyone opens robots.txt. The policy moved in five steps, per its own blog and docs.
| Date | What Cloudflare did |
|---|---|
| July 1, 2025 | Said it was changing its default to block AI crawlers unless they pay, and launched Pay Per Crawl as a private beta with allow, charge or block per crawler |
| August 4, 2025 | Accused Perplexity of using undeclared crawlers to dodge no-crawl rules, which Perplexity disputed |
| September 24, 2025 | Launched the Content Signals Policy, a robots.txt line for search, AI input and training |
| July 1, 2026 | Announced new AI traffic options for all customers, Free tier included |
| September 15, 2026 | New default for new domains, which blocks training and agent crawlers on pages that show ads |
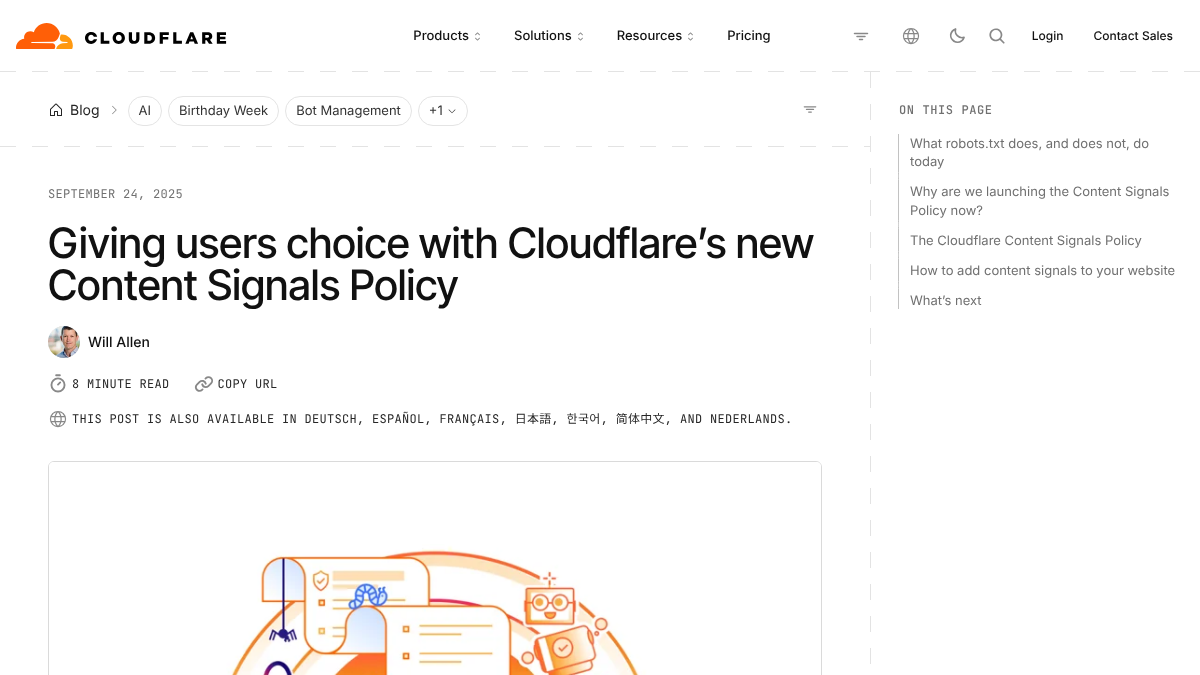
The September 15 change is narrower than a lot of the summaries made it sound. Cloudflare's post says the new default applies to "all new domains onboarding to Cloudflare." On those domains, pages that show ads block training and agent crawlers, while search crawlers stay allowed.
The real catch is mixed crawlers. Bots doing both search and training, like Googlebot, Applebot and Bingbot, get blocked on any site that chooses to block training. Every site can still change these defaults, since Cloudflare's AI Crawl Control docs, updated August 14, 2026, list it on every plan. If your domain joined before September 15, check your own settings instead of guessing. Our Bot Fight Mode guide covers the switches that block crawlers by accident.
What to do with this
Most businesses that want to be found leave search crawlers and user fetchers open, then make a separate call on training. Our post on whether to block AI crawlers walks through that decision. For how other sites handle it, the AI crawler access statistics show how many block GPTBot by name.
Whatever you decide, check that it held. A CDN switch or security plugin can block a bot that robots.txt allows, and neither shows up in the file. Budget an hour to review the file and your CDN's bot settings, then about 30 minutes a month to confirm the bots you allowed still arrive. Both are rough estimates.
A crawler can stop reaching your pages for weeks before anyone notices, which is why tracking AI bot visits is worth a light monthly look.
Seeing crawlers and citations together
You can do all of this by hand with vendor docs and a log file. Or RankControl can watch it for you. Our analytics log AI crawler visits per page and keep them separate from your human visitors, with a check that flags whether your host or robots.txt is turning any away.
Our AI visibility tracking then checks up to 50 buyer questions every week across seven AI engines, so you can see whether open doors are turning into real citations. There's one flat plan at $400/mo with a 7-day free trial.
Your competitors are getting cited by AI. You're not.
Every day without citation tracking is a day your competitors pull ahead in ChatGPT, Perplexity, and Claude.